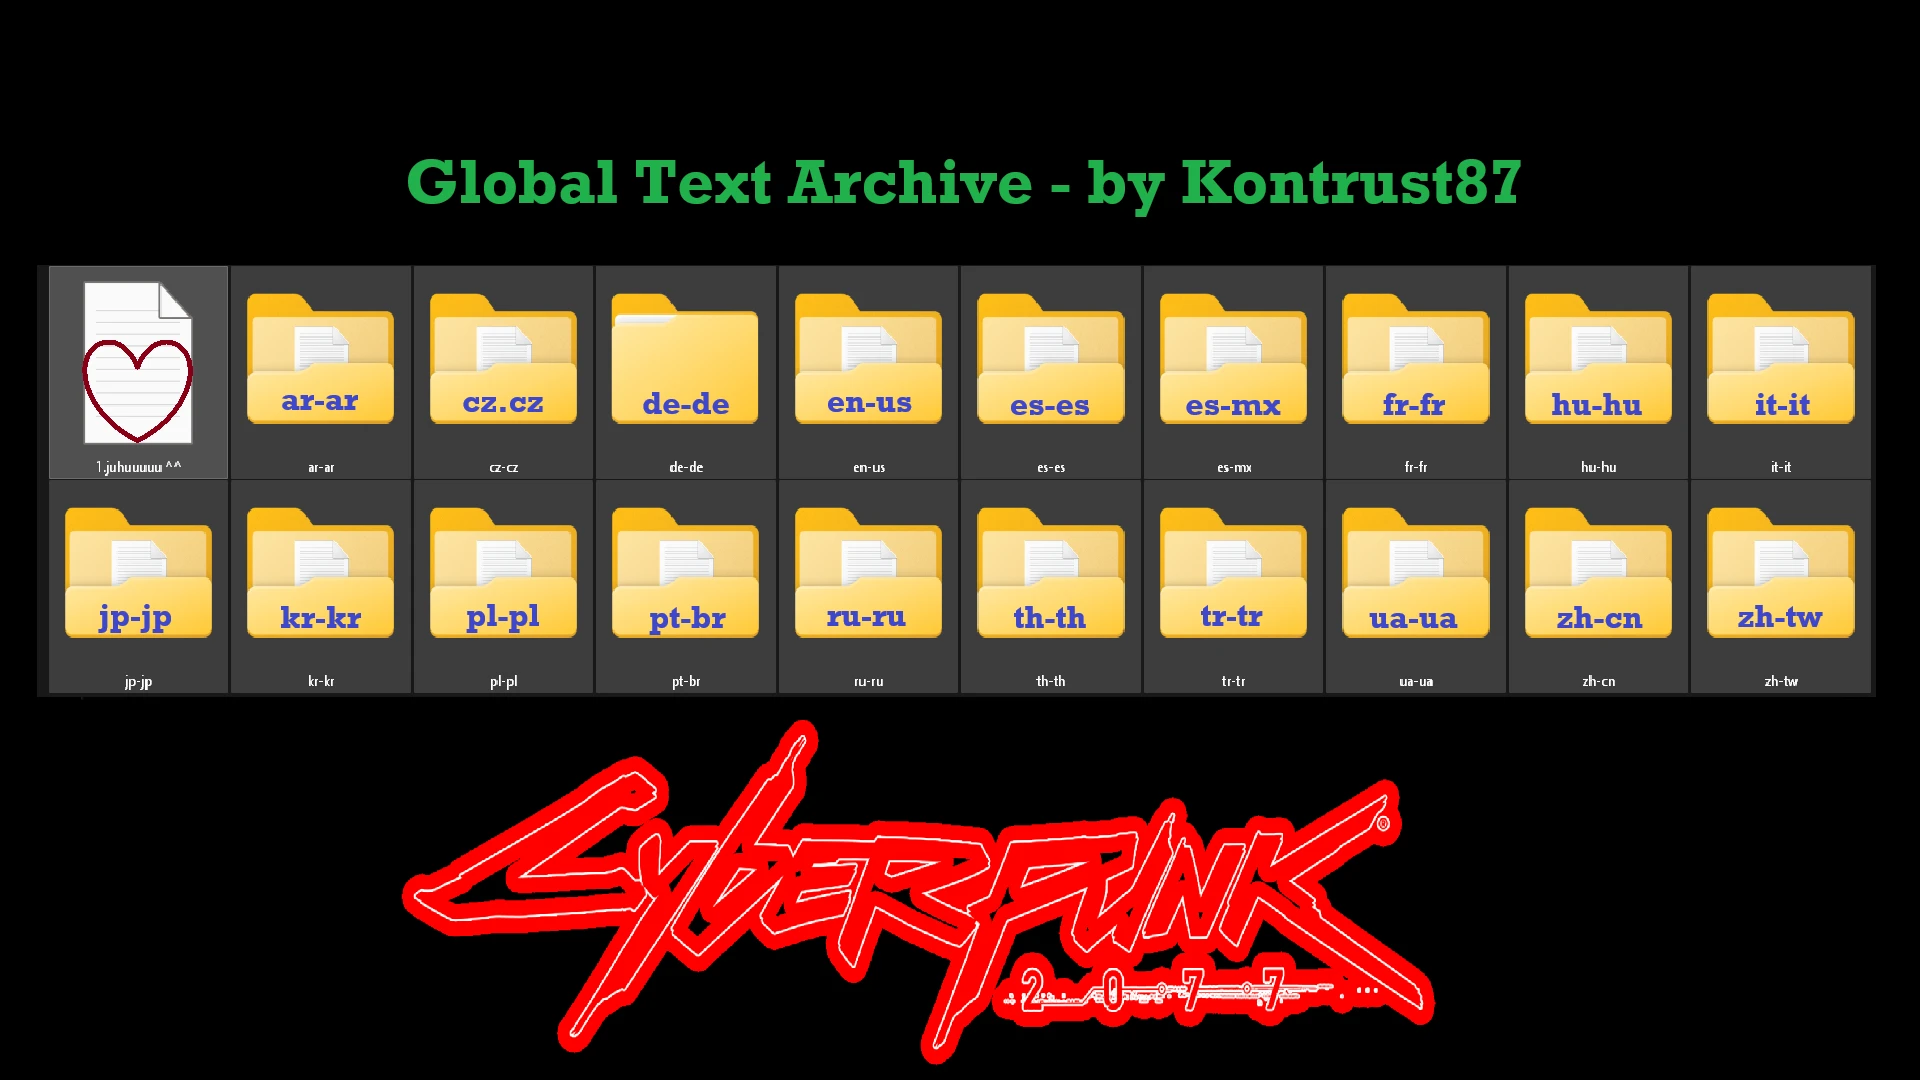
赛博朋克2077全局文本存档 - 19种语言完全排序(V4)
包含全部19种官方游戏语言碎片的大型、完全提取并整理过的文本存档。排序并本地化翻译的文件夹结构。非常适合故事猎手、翻译者和模组制作者!可节省12小时以上的提取工作。然而,我目前正费尽心机修复文件夹。
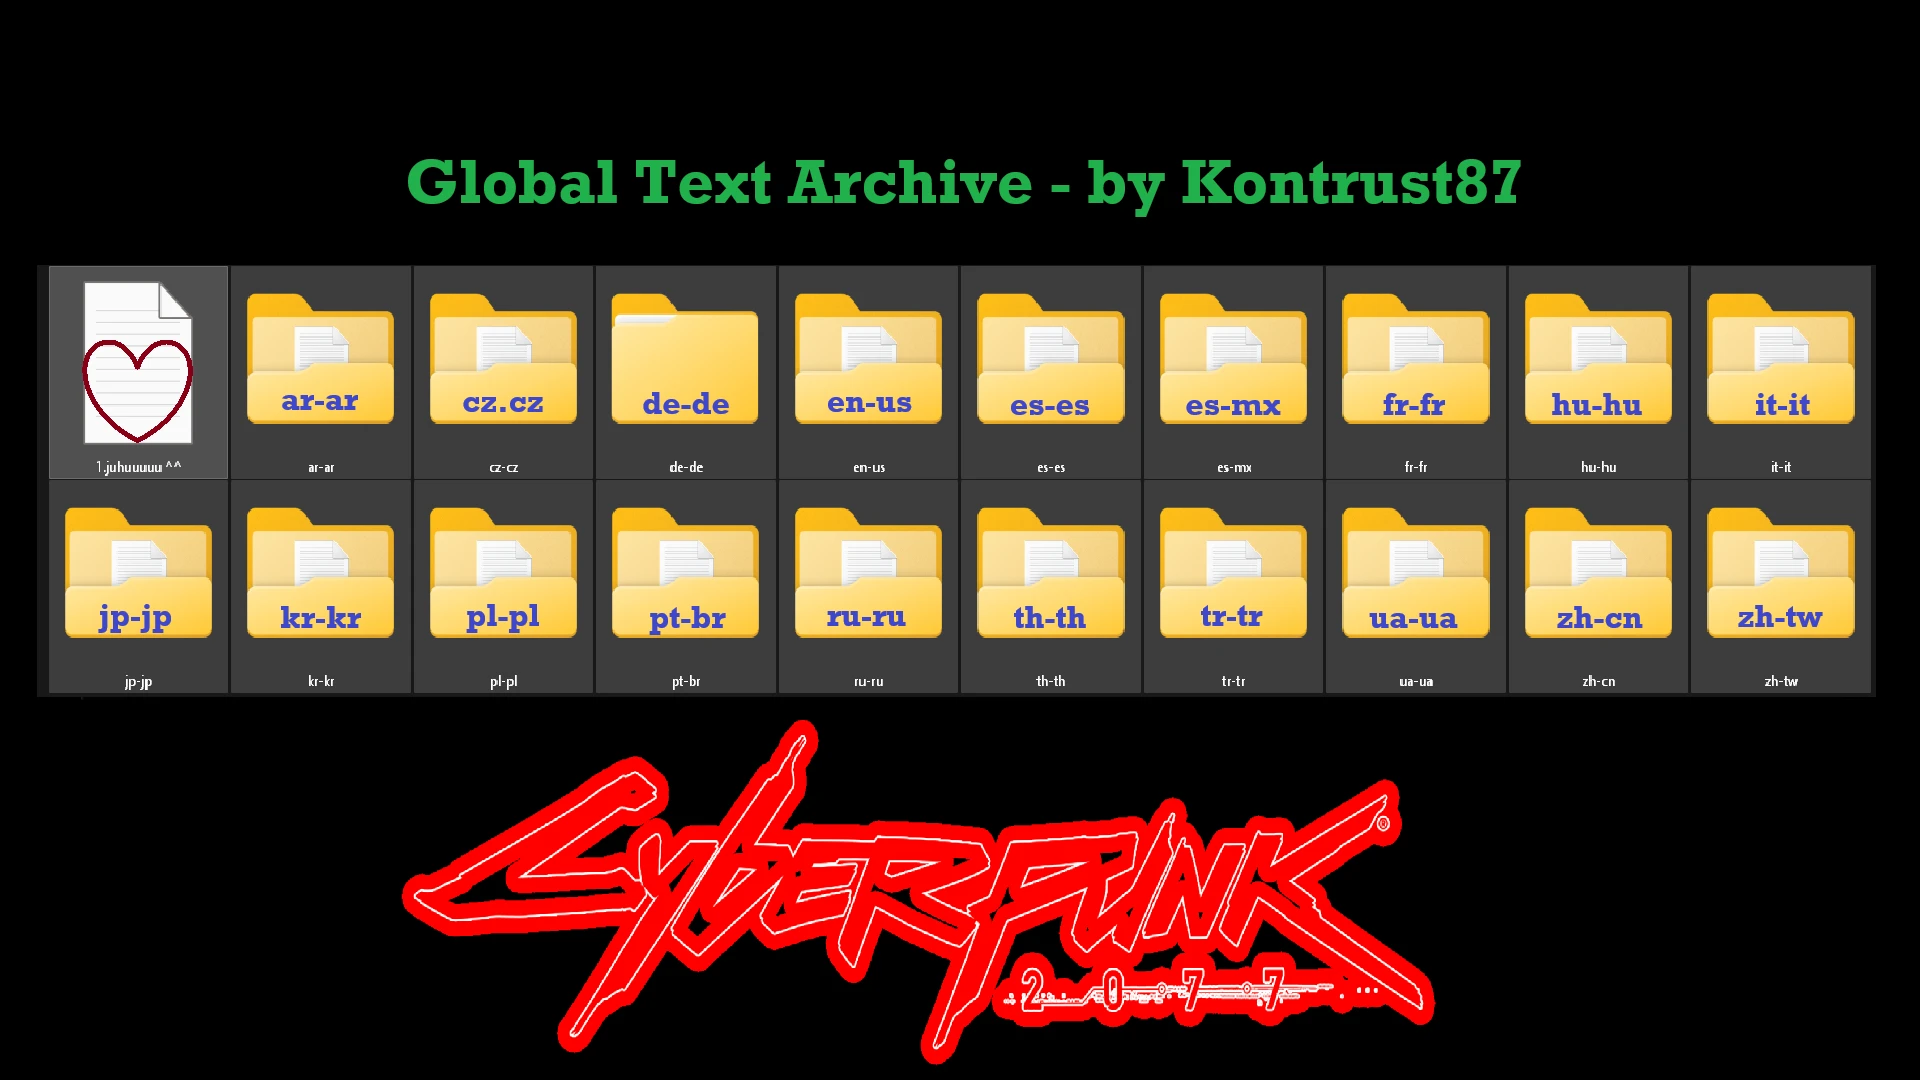 查看大图
================================================================================
⚠️ 重要更新(请阅读) ⚠️
不幸的是,文件夹 04 ❌ 和 05 ❌ 中的文件目前存在损坏问题。
这是由于我刚刚才注意到的一个脚本错误。我当时非常高兴能够收集到所有的碎片及其标题,
并错误地认为开发者会在其余部分使用相同的逻辑。
文件夹 03_Journal_SPLITTER ✅ 和文件夹 06_Computer_MAILS ✅ 是完全正确的。
================================================================================
描述
这个模组提供了来自《赛博朋克2077》及其《往日之影》扩展包中碎片的全面、完全提取且整理有序的数据库。它包含全部 19 种官方游戏语言。
这个档案包旨在为模组制作者、背景故事研究者和翻译人员提供一个节省时间的开发资源。它消除了通过 WolvenKit 进行数小时手动提取的需要。
主要功能
在每个 19 种语言文件夹内,您将找到四个主要类别,其结构旨在实现最大效用:
✅ * 03_Journal_SPLITTER:所有碎片和日志文本的完整数据库。文件夹名称已完全翻译为其母语,便于导航。
❌ * 04_SMS_NPC [当前损坏]:来自 NPC 的每一条收发短信。角色文件夹名称保留英文/拉丁文本,以保证与开发工具的全局兼容性。
❌ * 05_Codex_LEXIKON [当前损坏]:所有数据库条目、派系和背景故事信息的全面数据库。子文件夹已翻译为母语。
✅ * 06_Computer_MAILS:笔记本电脑文件、终端日志和电子邮件。严格按技术开发者 ID 组织,以防止游戏数据库资产冲突。
安装说明
这是一个原始的文本资源包。它不需要放入您的游戏文件夹。
1. 下载档案包。
2. 将 ZIP 文件解压到您电脑上的任意位置。
3. 打开您偏好的语言文件夹,以阅读或使用原始的 .txt 资源。
要求
* 无。这是一个独立的 .txt 文件资源档案。
来自 Kontrust87 的附言
我为这个项目倾尽了全力。由于我已经深入参与了这个为我自己的项目而进行的大规模提取任务,我决定再接再厉,顺便为整个社区完成全部 19 种语言。
我真心希望您喜欢使用这个档案包,并希望它能为您自己的旅程和模组节省大量时间!夜之城一路平安,伙计们!🦾
为什么短信如此棘手:嵌套 ID 而非纯文本。 虽然“碎片”通常存储为连续的块,但 .json 文件中的短信通常由无数交叉引用(本地化键或十六进制 ID)组成。在游戏中,一条文本通常由发送者 ID、接收者 ID、时间戳和实际文本片段动态组装而成;如果您的脚本只是简单地读取语言文件,它就缺少这些必要的链接。
以下是折叠内容中的源代码。我怀疑我卡在了短信和数据库部分。
[折叠内容]
import os
import json
PROJECT_DIR = r"C:\Users\Admin\Desktop\Cyberpunk Arbeit\Alle_Texte_in_Cyberpunk\01_ROHDATEN_AUS_SPIEL"
CURRENT_DIR = os.path.dirname(os.path.abspath(file))
MAIN_WORKSPACE = os.path.dirname(CURRENT_DIR)
OUTPUT_SHARDS = os.path.join(MAIN_WORKSPACE, "03_FERTIGE_TEXTE_FUER_Journal_SPLITTER")
OUTPUT_SMS = os.path.join(MAIN_WORKSPACE, "04_FERTIGE_TEXTE_FUER_SMS_NPC")
OUTPUT_CODEX = os.path.join(MAIN_WORKSPACE, "05_FERTIGE_TEXTE_FUER_Codex_LEXIKON")
OUTPUT_MAILS = os.path.join(MAIN_WORKSPACE, "06_FERTIGE_TEXTE_FUER_Computer_MAILS")
def load_json(filepath):
if os.path.exists(filepath):
try:
with open(filepath, 'r', encoding='utf-8') as f: return json.load(f)
except Exception as e: print(f"[WARNUNG] Fehler beim Laden: {e}")
return None
def find_exact_file(root_folder, must_contain, extension):
for root, dirs, files in os.walk(root_folder):
if "archiv" in root.lower(): continue
for file in files:
if must_contain.lower() in file.lower() and file.lower().endswith(extension):
if "journal" in must_contain.lower() and "onscreen" in file.lower(): continue
return os.path.join(root, file)
return None
def parse_text_entries(data):
entries = {}
def scan_dict(node):
if isinstance(node, dict):
if "femaleVariant" in node:
pk_val = node.get("primaryKey")
if isinstance(pk_val, dict) and "value" in pk_val: pk_val = pk_val["value"]
txt_val = node["femaleVariant"]
if isinstance(txt_val, dict) and "value" in txt_val: txt_val = txt_val["value"]
if pk_val and txt_val:
entries[str(pk_val).strip()] = str(txt_val).strip()
for v in node.values(): scan_dict(v)
elif isinstance(node, list):
for item in node: scan_dict(item)
scan_dict(data)
return entries
def clean_lockey(val):
if not val: return ""
val_str = str(val).strip()
if "lockey#" in val_str.lower():
return val_str.lower().replace("lockey#", "").strip()
return val_str
def scan_journal_all(node, current_cat="Sonstiges", current_contact="Unbekannt", codex_cat="Allgemeines", mail_owner="Computer_Dateien"):
"""扫描整个日志,并行查找所有 4 种内容类型"""
shards, sms_list, codex, mails = [], [], [], []
if isinstance(node, dict):
node_type = str(node.get("$type", ""))
node_id = str(node.get("id", "")).lower()
# 碎片和词典的类别映射
if node_id != "":
s_map = {"world": "世界", "literature": "文学", "religion": "宗教与哲学", "art": "艺术", "prospectus": "宣传册", "articles": "文章", "tech": "技术", "note": "笔记", "poetry": "诗歌", "lyric": "诗歌", "character": "夜之城人物", "cyberpsycho": "赛博精神病"}
for eng, de in s_map.items():
if eng in node_id: current_cat = de; break
c_map = {"vehicle": "载具", "car": "载具", "weapon": "武器与制造商", "gang": "帮派与派系", "corpo": "企业", "district": "区域与地点", "glossary": "术语表", "biography": "角色传记", "history": "历史与背景故事"}
for eng, de in c_map.items():
if eng in node_id: codex_cat = de; break
if "files" in node_id or "email" in node_id or "group" in node_id:
if node_id.strip(): mail_owner = node_id.replace("files", "").replace("emails", "").strip().title()
if "gameJournalContact" in node_type or "contact" in node_type.lower():
if "id" in node and isinstance(node["id"], str): current_contact = str(node["id"]).strip().title()
# 1. 匹配:CODEX / 词典(支持在同一节点或子节点中的描述)
if "gameJournalCodex" in node_type or "codex" in node_type.lower():
c_title = clean_lockey(node["title"].get("value")) if "title" in node and isinstance(node["title"], dict) else ""
# 在当前节点或嵌套节点中查找真正的文本 ID
c_body = ""
for k in ["description", "text", "content"]:
if k in node and isinstance(node[k], dict):
c_body = clean_lockey(node[k].get("value"))
if c_body: break
if c_body or c_title:
codex.append({"title_id": c_title, "body_id": c_body, "category": codex_cat})
# 2. 匹配:笔记本电脑文件与邮件
elif "gameJournalFile" in node_type or "gameJournalEmail" in node_type or "file" in node_type.lower() or "email" in node_type.lower():
t_id = clean_lockey(node["title"].get("value")) if "title" in node and isinstance(node["title"], dict) else ""
b_id = ""
for k in ["content", "description", "text"]:
if k in node and isinstance(node[k], dict):
b_id = clean_lockey(node[k].get("value"))
if b_id: break
if b_id or t_id: mails.append({"title_id": t_id, "body_id": b_id, "owner": mail_owner})
# 3. 匹配:普通碎片
elif "gameJournalOnscreen" in node_type or "onscreen" in node_type.lower():
t_id = clean_lockey(node["title"].get("value")) if "title" in node and isinstance(node["title"], dict) else ""
b_id = clean_lockey(node["description"].get("value")) if "description" in node and isinstance(node["description"], dict) else ""
s_id = clean_lockey(node["text"].get("value")) if "text" in node and isinstance(node["text"], dict) else ""
if t_id or b_id: shards.append({"title_id": t_id, "body_id": b_id, "sign_id": s_id, "category": current_cat})
# 4. 匹配:NPC 短信
elif "gameJournalPhoneMessage" in node_type or "phonemessage" in node_type.lower():
is_player = node.get("isPlayer", 0)
if str(is_player) in ["0", "False", "false"]:
msg_id = clean_lockey(node["text"].get("value")) if "text" in node and isinstance(node["text"], dict) else ""
if msg_id: sms_list.append({"msg_id": msg_id, "contact": current_contact})
for v in node.values():
if isinstance(v, (dict, list)):
s_res, m_res, c_res, e_res = scan_journal_all(v, current_cat, current_contact, codex_cat, mail_owner)
shards.extend(s_res); sms_list.extend(m_res); codex.extend(c_res); mails.extend(e_res)
elif isinstance(node, list):
for item in node:
s_res, m_res, c_res, e_res = scan_journal_all(item, current_cat, current_contact, codex_cat, mail_owner)
shards.extend(s_res); sms_list.extend(m_res); codex.extend(c_res); mails.extend(e_res)
return shards, sms_list, codex, mails
def extract_splitter():
print("正在启动赛博朋克全合一工作室(V4 - 词典更新)...")
main_dir, dlc_dir = os.path.join(PROJECT_DIR, "Hauptspiel"), os.path.join(PROJECT_DIR, "DLC")
main_text_path = find_exact_file(main_dir, "onscreens", ".json")
main_journal_path = find_exact_file(main_dir, "journal", ".json")
dlc_text_path = find_exact_file(dlc_dir, "ep1_onscreens", ".json")
dlc_journal_path = find_exact_file(dlc_dir, "ep1_cooked", ".json") or find_exact_file(dlc_dir, "cooked_journal", ".json")
print("\n[INFO] 正在读取语言文件...")
text_map = {}
for path in [main_text_path, dlc_text_path]:
if not path or not os.path.exists(path): continue
data = load_json(path)
if data:
found_map = parse_text_entries(data)
text_map.update(found_map)
print(f"-> 从 {os.path.basename(path)} 学习了 {len(found_map)} 行文本。")
print("\n[INFO] 正在分析开发者数据中的碎片、短信、邮件和词典...")
j_shards, j_sms, j_codex, j_mails = [], [], [], []
for j_path in [main_journal_path, dlc_journal_path]:
if not j_path or not os.path.exists(j_path): continue
j_data = load_json(j_path)
if j_data:
s_f, m_f, c_f, e_f = scan_journal_all(j_data)
j_shards.extend(s_f); j_sms.extend(m_f); j_codex.extend(c_f); j_mails.extend(e_f)
print(f"-> 成功处理了来自 {os.path.basename(j_path)} 的链接。")
# === 处理 1:碎片 ===
print(f"\n[INFO] 正在组装 {len(j_shards)} 个碎片...")
shard_count, used_shards = 0, set()
for pkg in j_shards:
body_id = pkg["body_id"]
title_id = pkg["title_id"]
sign_id = pkg["sign_id"]
category = pkg["category"]
title_text = text_map.get(title_id, "").replace("\\n", "\n").strip()
body_text = text_map.get(body_id, "").replace("\\n", "\n").strip()
sign_text = text_map.get(sign_id, "").replace("\\n", "\n").strip()
if not body_text and title_text:
body_text, title_text, body_id = title_text, "", title_id
if not body_text or body_id in used_shards: continue
used_shards.add(body_id)
final_content = f"{body_id}\n\n"
if title_text: final_content += f"{title_text.upper()}\n\n"
final_content += body_text
if sign_text: final_content += f"\n\n{sign_text}"
cat_dir = os.path.join(OUTPUT_SHARDS, category)
os.makedirs(cat_dir, exist_ok=True)
name_source = title_text if title_text else body_text.split("\n")
clean_name = "".join([c for c in name_source if c.isalpha() or c.isspace() or c.isdigit()]).strip()
file_name = f"{body_id}{clean_name[:20]}.txt" if clean_name else f"Splitter{body_id}.txt"
with open(os.path.join(cat_dir, file_name), "w", encoding="utf-8") as out_f: out_f.write(final_content)
shard_count += 1
# === 处理 2:NPC 短信 ===
print(f"[INFO] 正在按角色排序收到的短信...")
sms_count, used_sms = 0, set()
for msg in j_sms:
msg_id = msg["msg_id"]
contact = msg["contact"]
sms_text = text_map.get(msg_id, "").replace("\\n", "\n").strip()
if not sms_text or msg_id in used_sms: continue
used_sms.add(msg_id)
final_sms_content = f"{msg_id}\n\n{sms_text}"
char_dir = os.path.join(OUTPUT_SMS, contact)
os.makedirs(char_dir, exist_ok=True)
clean_sms_name = "".join([c for c in sms_text.split("\n") if c.isalpha() or c.isspace() or c.isdigit()]).strip()
sms_file_name = f"{msg_id}{clean_sms_name[:20]}.txt" if clean_sms_name else f"SMS{msg_id}.txt"
with open(os.path.join(char_dir, sms_file_name), "w", encoding="utf-8") as out_f: out_f.write(final_sms_content)
sms_count += 1
# === 处理 3:CODEX / 词典 ===
print(f"[INFO] 正在按类别排序词典词条...")
codex_count, used_codex = 0, set()
for c_entry in j_codex:
body_id = c_entry["body_id"]
title_id = c_entry["title_id"]
category = c_entry["category"]
title_text = text_map.get(title_id, "").replace("\\n", "\n").strip()
body_text = text_map.get(body_id, "").replace("\\n", "\n").strip()
if not body_text and title_text:
body_text, title_text, body_id = title_text, "", title_id
if not body_text or body_id in used_codex: continue
used_codex.add(body_id)
final_c = f"{body_id}\n\n"
if title_text: final_c += f"{title_text.upper()}\n\n"
final_c += body_text
os.makedirs(os.path.join(OUTPUT_CODEX, category), exist_ok=True)
lines = body_text.split("\n")
name_source = title_text if title_text else (lines if lines else "Codex")
c_name = "".join([c for c in name_source if c.isalpha() or c.isspace() or c.isdigit()]).strip()
with open(os.path.join(OUTPUT_CODEX, category, f"{body_id}{c_name[:20]}.txt"), "w", encoding="utf-8") as f: f.write(final_c)
codex_count += 1
# === 处理 4:电脑邮件 ===
print(f"[INFO] 正在按所有者排序笔记本电脑邮件和系统文件...")
mail_count, used_mails = 0, set()
for mail in j_mails:
body_id = mail["body_id"]
title_id = mail["title_id"]
owner = mail["owner"]
title_text = text_map.get(title_id, "").replace("\\n", "\n").strip()
body_text = text_map.get(body_id, "").replace("\\n", "\n").strip()
if not body_text and title_text:
body_text, title_text, body_id = title_text, "", title_id
if not body_text or body_id in used_mails: continue
used_mails.add(body_id)
final_m = f"{body_id}\n\n"
if title_text: final_m += f"{title_text.upper()}\n\n"
final_m += body_text
os.makedirs(os.path.join(OUTPUT_MAILS, owner), exist_ok=True)
lines = body_text.split("\n")
name_source = title_text if title_text else (lines if lines else "Mail")
c_name = "".join([c for c in name_source if c.isalpha() or c.isspace() or c.isdigit()]).strip()
with open(os.path.join(OUTPUT_MAILS, owner, f"{body_id}{c_name[:20]}.txt"), "w", encoding="utf-8") as f: f.write(final_m)
mail_count += 1
print(f"\n===========================================================")
print(f"[成功] 已忠实地合并了 {shard_count} 个碎片!")
print(f"[成功] 已提取了 {sms_count} 条收到的 NPC 消息!")
print(f"[成功] 已整理了 {codex_count} 个词典词条!")
print(f"[成功] 已按所有者排序了 {mail_count} 封电脑邮件!")
print(f"\n-> 档案已在 {MAIN_WORKSPACE} 就绪")
print(f"===========================================================")
input("\n按回车键关闭...")
if name == "main":
extract_splitter()
[/折叠内容]
💥 💥 💥 这正是我费了这么大劲的原因。也许其他人能够成功地从赛博朋克源代码中提取短信和索引数据库。💪
https://www.nexusmods.com/cyberpunk2077/mods/30884?tab=description <-- 我的项目,为我做的德语配音
正在加载版本记录…
正在加载评论…
评论在新手盒子客户端中发表,这里同步展示。